
Catch Python performance regressions in CI deterministically, so your benchmark gate stops crying wolf.
Why
Wall-clock benchmarks are noisy enough to make a pull-request gate unreliable. Run the same unchanged code seven times and time it, then count the operations it performed on those same runs:
wall-clock       : 2.06ms  2.06ms  2.20ms  2.04ms  2.06ms  2.05ms  2.17ms   → 3.1% spread
operation counts : 3196    3196    3196    3196    3196    3196    3196     → 0.0% spread
That 3.1% is on an idle machine, the best case. On wall-clock you either set the threshold tight and get flaky failures, or set it wide and miss real regressions.
pyxtrace counts operations (function calls and lines executed) instead of measuring time. Those counts are byte-for-byte reproducible, so a 10% threshold actually means something.
Install
pip install pyxtraceOne dependency (rich). Python 3.10+.
Use
With your test suite: nothing to set up
pyxtrace diff main HEAD # or `pyxtrace diff main` for uncommitted workWith no runs recorded, diff uses your pytest suite as the workload. It
checks out both commits into temporary git worktrees (your checkout is never touched),
runs the head's tests against both versions of the code, and counts each test on its own.
Each regression is tied to the diff: a function the change edited is marked
← changed in this diff, and one that only got busier names the changed
functions on its call path.
With a workload script
pyxtrace examples/orders.py      # → .pyxtrace/<commit sha>.pyxt
# ... commit your change ...
pyxtrace examples/orders.py
pyxtrace diff HEAD~1 HEAD        # any git ref, or a .pyxt path
diff exits 1 when something regressed, so it drops straight into CI.
What a caught regression looks like
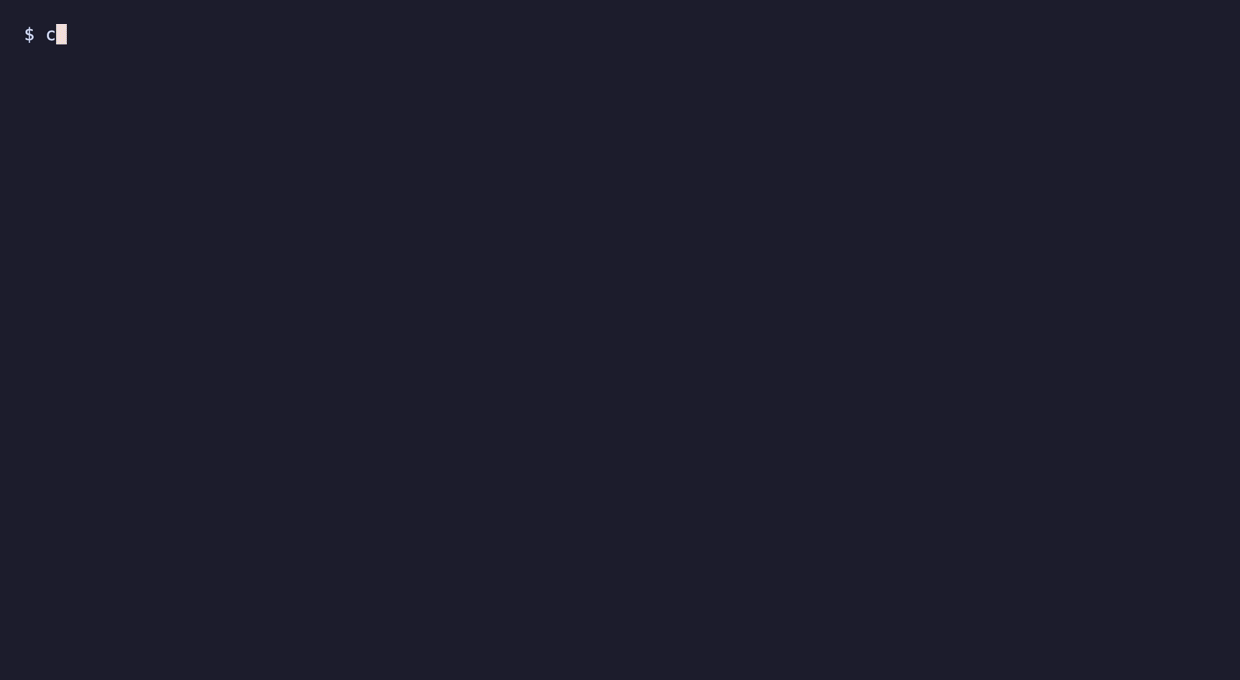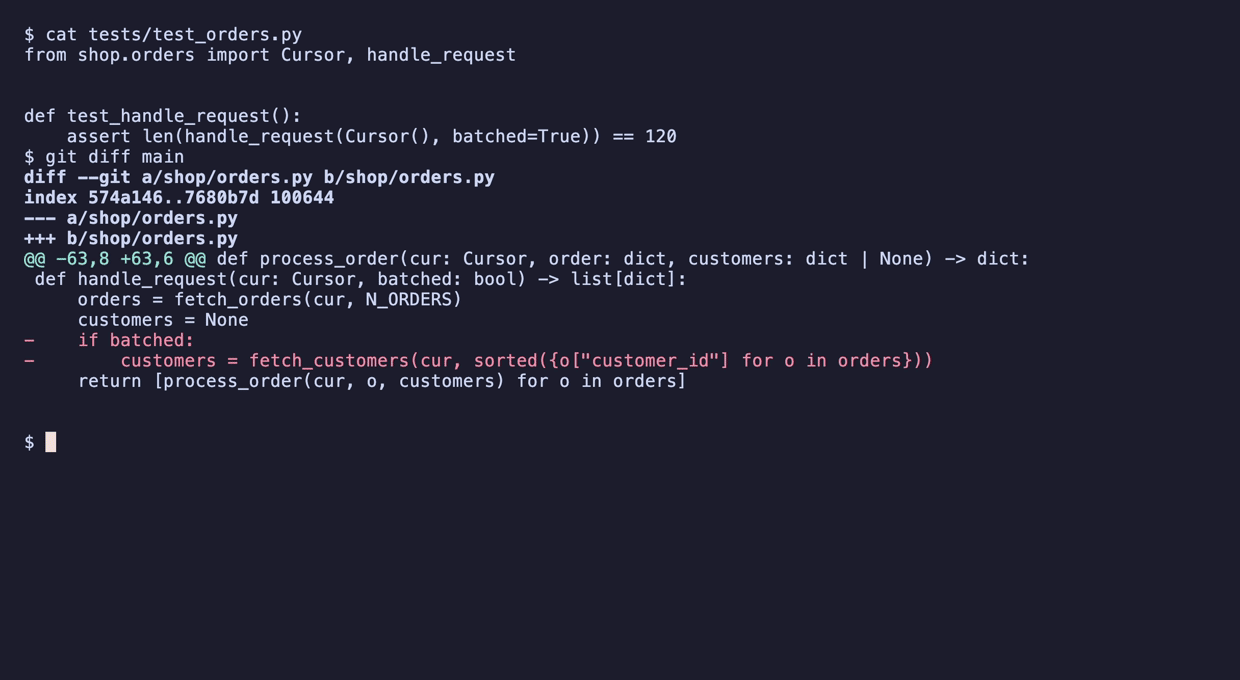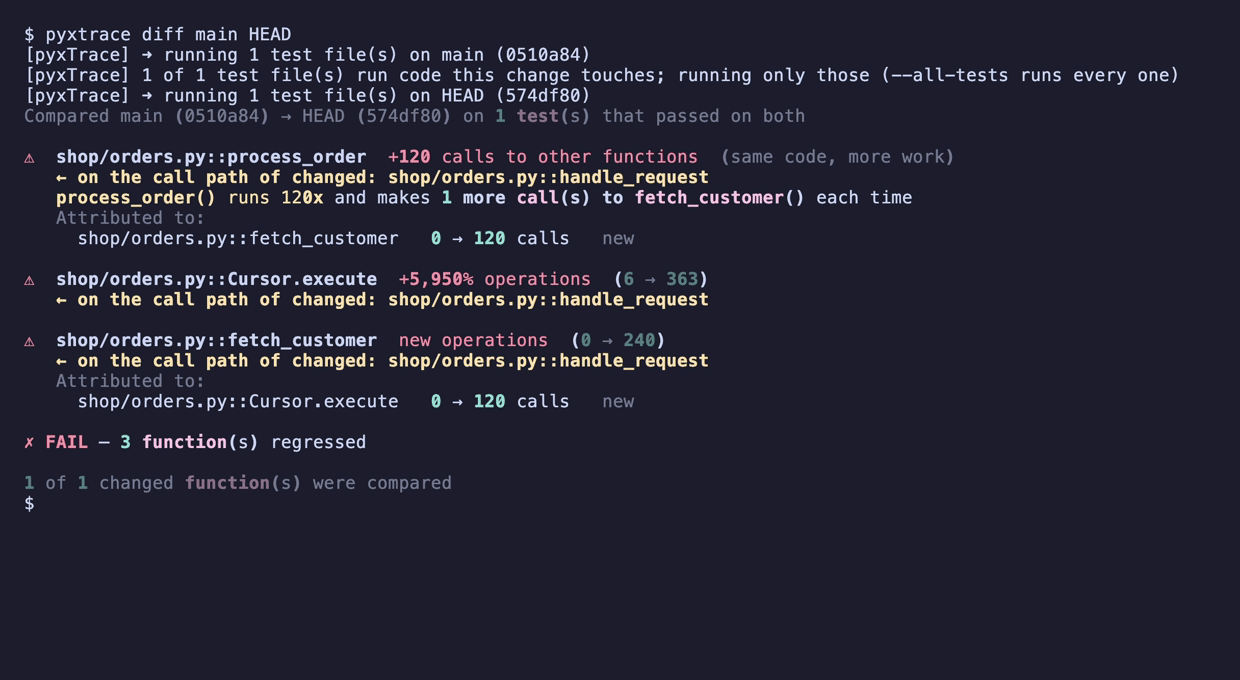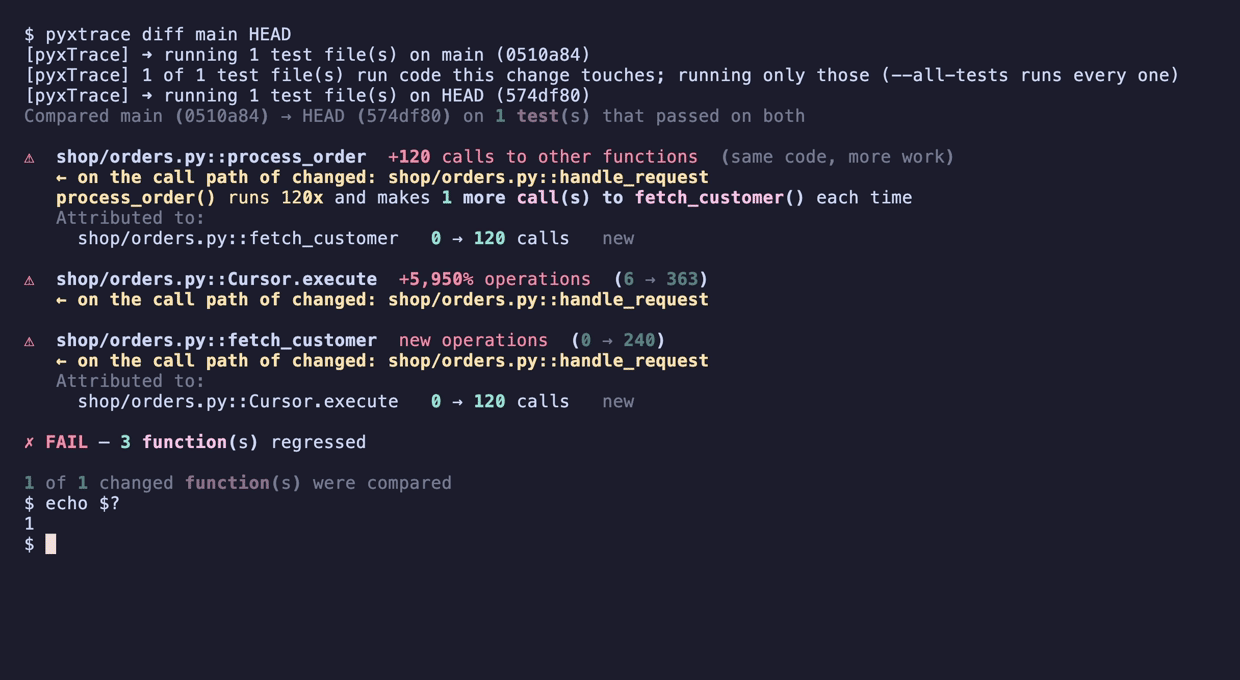
⚠  examples/orders.py::process_order  +120 calls to other functions  (same code, more work)
   process_order() runs 120x and makes 1 more call(s) to fetch_customer() each time
   Attributed to:
     examples/orders.py::fetch_customer   0 → 120 calls   new

⚠  examples/orders.py::Cursor.execute  +5,950% operations  (6 → 363)

⚠  examples/orders.py::fetch_customer  new operations  (0 → 240)
   Attributed to:
     examples/orders.py::Cursor.execute   0 → 120 calls   new

✗ FAIL — 3 function(s) regressed
Every line is arithmetic over exact counts. There is no confidence score because there is nothing to be uncertain about.
In CI
With a test suite, the gate is one step after installing your project's test dependencies:
- uses: actions/checkout@v4
  with: { fetch-depth: 0 }                  # the base commit has to be present
- run: pip install pyxtrace pytest -e .
- uses: actions/cache@v4                    # the base side, counted once per test file
  with:
    path: .pyxtrace/tests
    key: pyxtrace-${{ runner.os }}-${{ github.event.pull_request.base.sha }}
    restore-keys: pyxtrace-${{ runner.os }}-
- run: pyxtrace diff ${{ github.event.pull_request.base.sha }} HEAD --stability-runs 2
The base side's results are cached per test file, keyed by everything the counts
depend on, so a second diff against the same base runs only the head.
--stability-runs 2 leaves out any test whose counts differ between two runs,
so a test driven by the clock cannot fail the gate.
The workload-script recipe is in the README.
Limits
pyxtrace counts Python operations. Work inside C (regexes, NumPy, database drivers, I/O waits) is invisible to it, so it is strongest on pure-Python CPU-bound code: parsers, template engines, serializers, business logic. Counts are exact per Python minor version, and they are a proxy for cost, not a measure of it. All the limits, stated plainly.
When to use something else
| You want | Use |
|---|---|
| Profile a running production process | py-spy |
| Find where memory is allocated | memray |
| A readable one-off wall-clock profile | pyinstrument |
| A timeline / flame-graph UI | VizTracer |
| Know whether this PR made things slower | pyxtrace |